
标签:res img contents bs4 pre encoding 分享 style html
import requests
from bs4 import BeautifulSoup

gzccurl = ‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘
res = requests.get(gzccurl)
res.encoding=‘utf-8‘

soup = BeautifulSoup(res.text,‘html.parser‘)

for news in soup.select(‘li‘):
    if len(news.select(‘.news-list-title‘))>0:
        title = news.select(‘.news-list-title‘)[0].text#标题
        url = news.select(‘a‘)[0][‘href‘]#链接
        time = news.select(‘.news-list-info‘)[0].contents[0].text
        source = news.select(‘.news-list-info‘)[0].contents[1].text

        #详情
        #resd = requests.get(url)
        #res.encoding=‘utf-8‘
        #soupd = BeautifulSoup(res.text,‘html.parser‘)
        #detail = soupd.select(‘.show-content‘)

        print(time,‘\n‘,title,‘\n‘,url,‘\n‘,source,‘\n‘
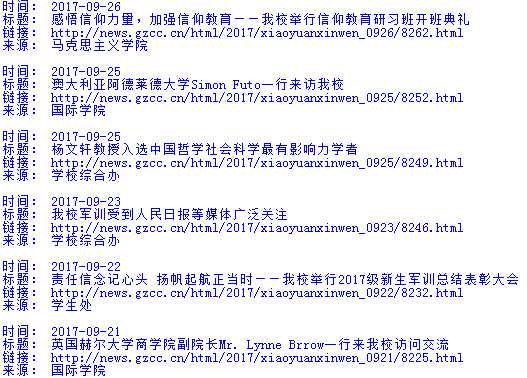
用requests库和BeautifulSoup4库爬取新闻列表
标签:res img contents bs4 pre encoding 分享 style html
原文地址:http://www.cnblogs.com/diaowen/p/7607075.html
