
标签:ext text 分享 mode 完成 链接 新闻列表 count pre
1、获取单条新闻的#标题#链接#时间#来源#内容 #点击次数,并包装成一个函数。
2、获取一个新闻列表页的所有新闻的上述详情,并包装成一个函数。
3、获取所有新闻列表页的网址,调用上述函数。
4、完成所有校园新闻的爬取工作。
5、完成自己所选其他主题相应数据的爬取工作。
import requests
from bs4 import BeautifulSoup
from datetime import datetime
import re
res=requests.get(‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘)
res.encoding=‘utf-8‘
soup=BeautifulSoup(res.text,‘html.parser‘)

def getclick(newsurl):
    id=re.search(‘_(.*).html‘,newsurl).group(1).split(‘/‘)[1]
    clickurl=‘http://oa.gzcc.cn/api.php?op=count&id={}&modelid=80‘.format(id)
    click=int(requests.get(clickurl).text.split(‘.‘)[-1].lstrip("html(‘").rstrip("‘);"))
    return click

for news in soup.select(‘li‘):
    if len(news.select(‘.news-list-title‘))>0:
      title=news.select(‘.news-list-title‘)[0].text
      url=news.select(‘a‘)[0][‘href‘]
      time=news.select(‘.news-list-info‘)[0].contents[0].text
      laiyuan=news.select(‘.news-list-info‘)[0].contents[1].text

      resd=requests.get(url)
      resd.encoding=‘utf-8‘
      soupd=BeautifulSoup(resd.text,‘html.parser‘)
      detail=soupd.select(‘.show-content‘)[0].text
      click=getclick(url)

      print(title,url,time,laiyuan,click)
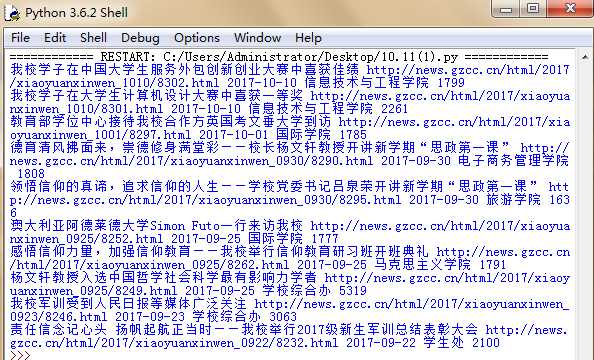
import requests
from bs4 import BeautifulSoup
from datetime import datetime
import re
res=requests.get(‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘)
res.encoding=‘utf-8‘
soup=BeautifulSoup(res.text,‘html.parser‘)

n=int(soup.select(‘.a1‘)[0].text.rstrip(‘条‘))
pages=n//10+1
for i in range(2,pages+1):
    pageurl=‘http://news.gzcc.cn/html/xiaoyuanxinwen/{}.html‘.format(i)
    print(pageurl)
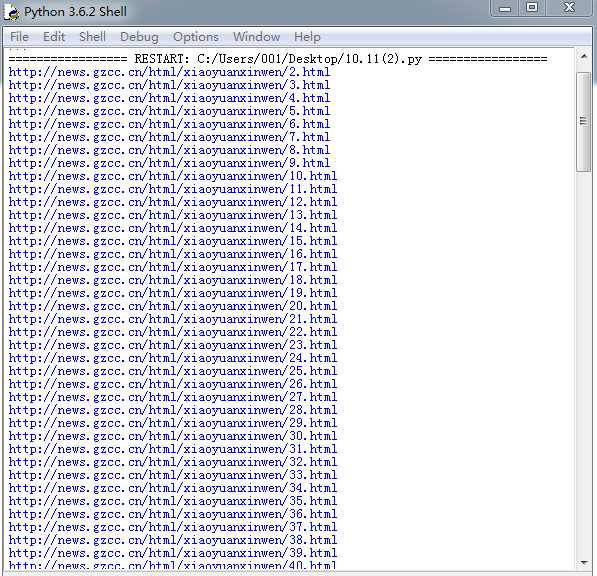
标签:ext text 分享 mode 完成 链接 新闻列表 count pre
原文地址:http://www.cnblogs.com/chenyuanzhao/p/7649087.html
