下载一长篇中文文章。
从文件读取待分析文本。
news = open(‘gzccnews.txt‘,‘r‘,encoding = ‘utf-8‘)
安装与使用jieba进行中文分词。
pip install jieba
import jieba
list(jieba.lcut(news))
生成词频统计
排序
排除语法型词汇,代词、冠词、连词
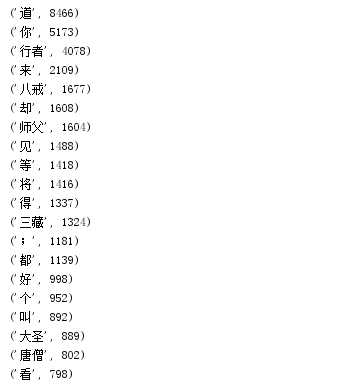
输出词频最大TOP20
# -*- coding : UTF-8 -*-
# -*- author : Kamchuen -*-

import jieba

exclude = {‘,‘,‘、‘,‘:‘,‘《‘,‘》‘,‘(‘,‘)‘,‘。‘,‘-‘}
txt = open(‘西游记.txt‘,‘r‘,encoding=‘utf-8‘)
article0 = txt.read()
article1 = list(jieba.lcut(article0))

symbol = {‘,‘,‘。‘,‘ ‘,‘:‘,‘“‘,‘”‘,‘\n‘,‘!‘,‘、‘,‘?‘,‘;‘‘你‘,‘ ‘,‘我‘,‘我们‘, ‘他‘, ‘他们‘, ‘我的‘, ‘他的‘, ‘你的‘, ‘呀‘, ‘和‘, ‘是‘,‘的‘,‘啊‘,‘?‘,‘在‘,‘了‘,           ‘说‘,‘去‘,‘与‘,‘不‘,‘是‘,‘、‘,‘也‘,‘又‘,‘!‘,‘着‘,‘儿‘,‘这‘,‘到‘,‘就‘, ‘\n‘,‘(‘,‘)‘,‘那‘,‘有‘,‘上‘,‘便‘,‘和‘,‘只‘,‘要‘,‘小‘,‘罢‘,‘那里‘,           ‘…‘,‘一个‘,‘?‘,‘人‘,‘把‘,‘被‘}
article2 = {}
for a in article1:
    article2[a] = article2.get(a,0)+1

for b in symbol:
    if b in article2:
        del  article2[b]

article3 = sorted(article2.items(),key=lambda x:x[1],reverse=True)
for c in range(20):
    print(article3[c])
结果截图: