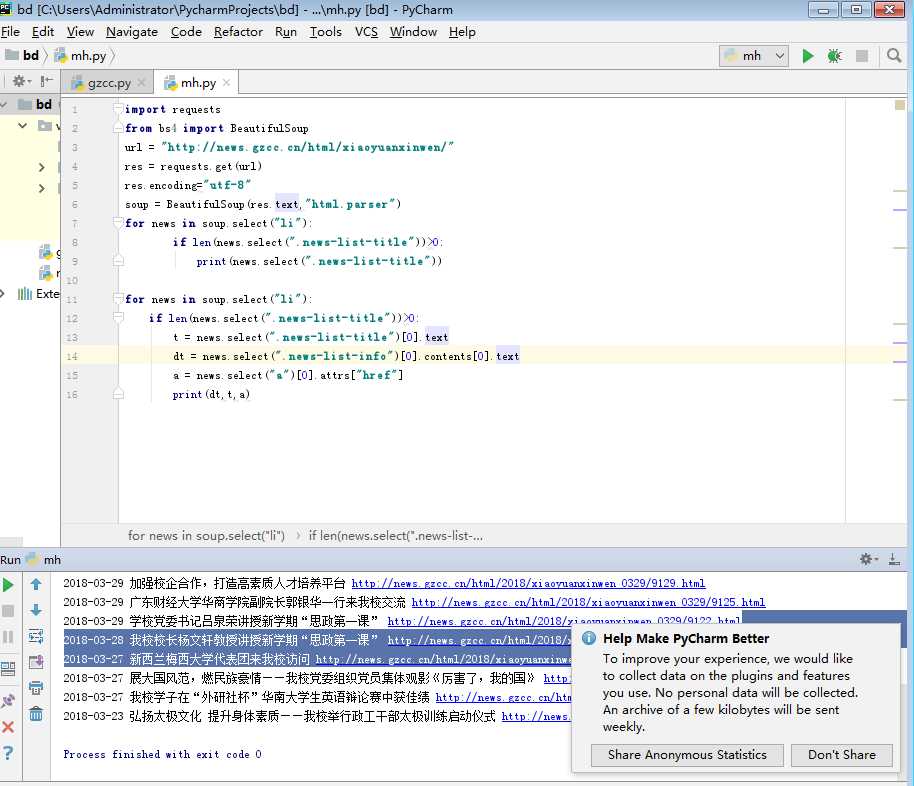
1. 用requests库和BeautifulSoup库,爬取校园新闻首页新闻的标题、链接、正文。
2. 分析字符串,获取每篇新闻的发布时间,作者,来源,摄影等信息。
import requests
from bs4 import BeautifulSoup
from datetime import datetime

url = ‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘
res = requests.get(url)
res.encoding = ‘utf-8‘
soup = BeautifulSoup(res.text,‘html.parser‘)
for news in soup.select(‘li‘):
    if len(news.select(‘.news-list-title‘))>0:
        t = news.select(‘.news-list-title‘)[0].text
        dt = news.select(‘.news-list-info‘)[0].contents[0].text
        a = news.select(‘a‘)[0].attrs[‘href‘]
        print(dt,t,a)#爬取校园新闻首页新闻的标题、链接
        res2 = requests.get(a)
        res2.encoding = ‘utf-8‘
        soup2 = BeautifulSoup(res2.text, ‘html.parser‘)
        te = soup2.select(‘#content‘)[0].text
        print(te)#爬取校园新闻首页新闻的正文

        ifd = soup2.select(‘.show-info‘)[0].text
        dt2 = ifd.lstrip(‘发布时间:‘)[:19]
        print(dt2)#获取每篇新闻的发布时间

        i = ifd.find(‘作者:‘)
        if i>0:
            s = ifd[ifd.find(‘作者:‘):].split()[0].lstrip(‘作者:‘)
            print(s)#获取每篇新闻的作者。

        q = ifd.find(‘来源:‘)
        if q > 0:
            b = ifd[ifd.find(‘来源:‘):].split()[0].lstrip(‘来源:‘)
            print(b)#获取每篇新闻的来源。

        c = ifd.find(‘摄影:‘)
        if c > 0:
            n = ifd[ifd.find(‘摄影:‘):].split()[0].lstrip(‘摄影:‘)
            print(n)#获取每篇新闻的摄影。

        dtn = datetime.strptime(dt2,‘%Y-%m-%d %H:%M:%S‘)#将其中的发布时间由str转换成datetime类型。
        print(dtn)
        break
3. 将其中的发布时间由str转换成datetime类型。
import requests
from bs4 import BeautifulSoup
from datetime import datetime

gzccurl = ‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘
res = requests.get(gzccurl)
res.encoding=‘utf-8‘
soup = BeautifulSoup(res.text,‘html.parser‘)

for news in soup.select(‘li‘):
    if len(news.select(‘.news-list-title‘))>0:
        title = news.select(‘.news-list-title‘)[0].text#标题
        url = news.select(‘a‘)[0][‘href‘]#链接
        time = news.select(‘.news-list-info‘)[0].contents[0].text
        dt = datetime.strptime(time,‘%Y-%m-%d‘)
        source = news.select(‘.news-list-info‘)[0].contents[1].text#来源
        print(dt,‘\n‘,title,‘\n‘,url,‘\n‘,source,‘\n‘)
