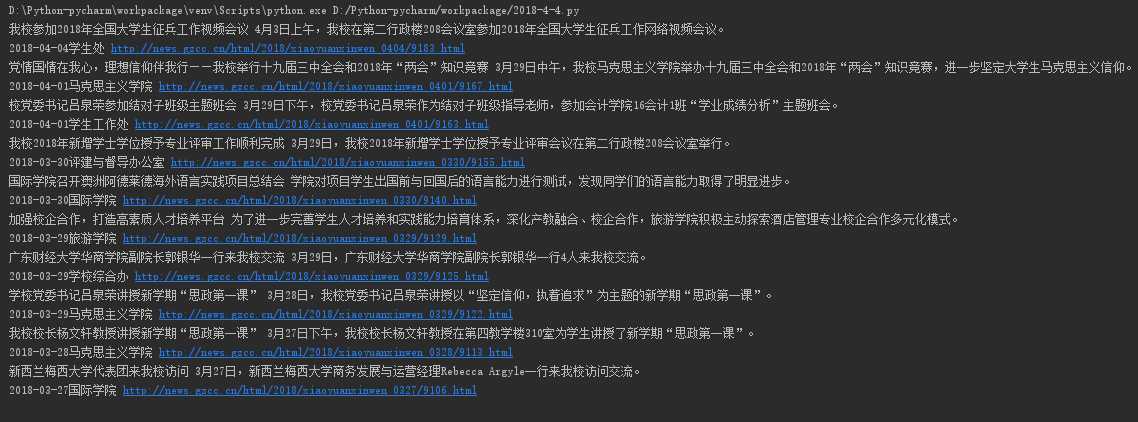
1. 用requests库和BeautifulSoup库,爬取校园新闻首页新闻的标题、链接、正文、show-info。
#coding=utf-8
import requests
from bs4 import BeautifulSoup

res=requests.get(‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘)
res.encoding=‘utf-8‘
soup=BeautifulSoup(res.text,‘html.parser‘)
soup

# print(soup)

for i in soup.select(‘li‘):
    if len(i.select(‘.news-list-title‘))>0:
        x=i.select(‘.news-list-title‘)[0].text
        y=i.select(‘.news-list-description‘)[0].text
        z=i.select(‘.news-list-info‘)[0].text
        p = i.select(‘a‘)[0].attrs[‘href‘]
        print(x,y)
        print(z,p)
截图:
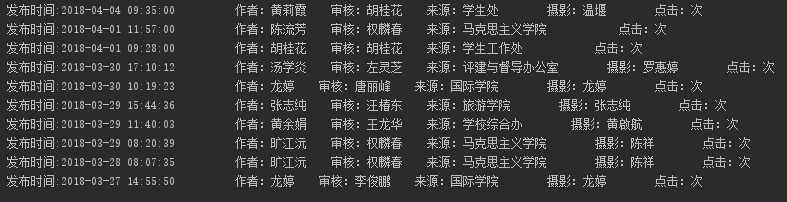
2. 分析info字符串,获取每篇新闻的发布时间,作者,来源,摄影等信息。
for i in soup.select(‘li‘):
    if len(i.select(‘.news-list-title‘))>0:
     a=i.select(‘.news-list-title‘)[0].text
     b=i.select(‘.news-list-description‘)[0].text
     # c=i.a.attrs[‘href‘]
     c=i.select(‘a‘)[0].attrs[‘href‘]
     read=requests.get(c)
     read.encoding=‘utf-8‘
     soupSecond=BeautifulSoup(read.text,‘html.parser‘)
     d=soupSecond.select(‘#content‘)[0].text
     print(soupSecond.select(‘.show-info‘)[0].text)
截图: